DATASYNTH
Human-in-the-loop EDA platform streamlining data preprocessing and synthetic data generation using Gaussian Copulas and SDV.
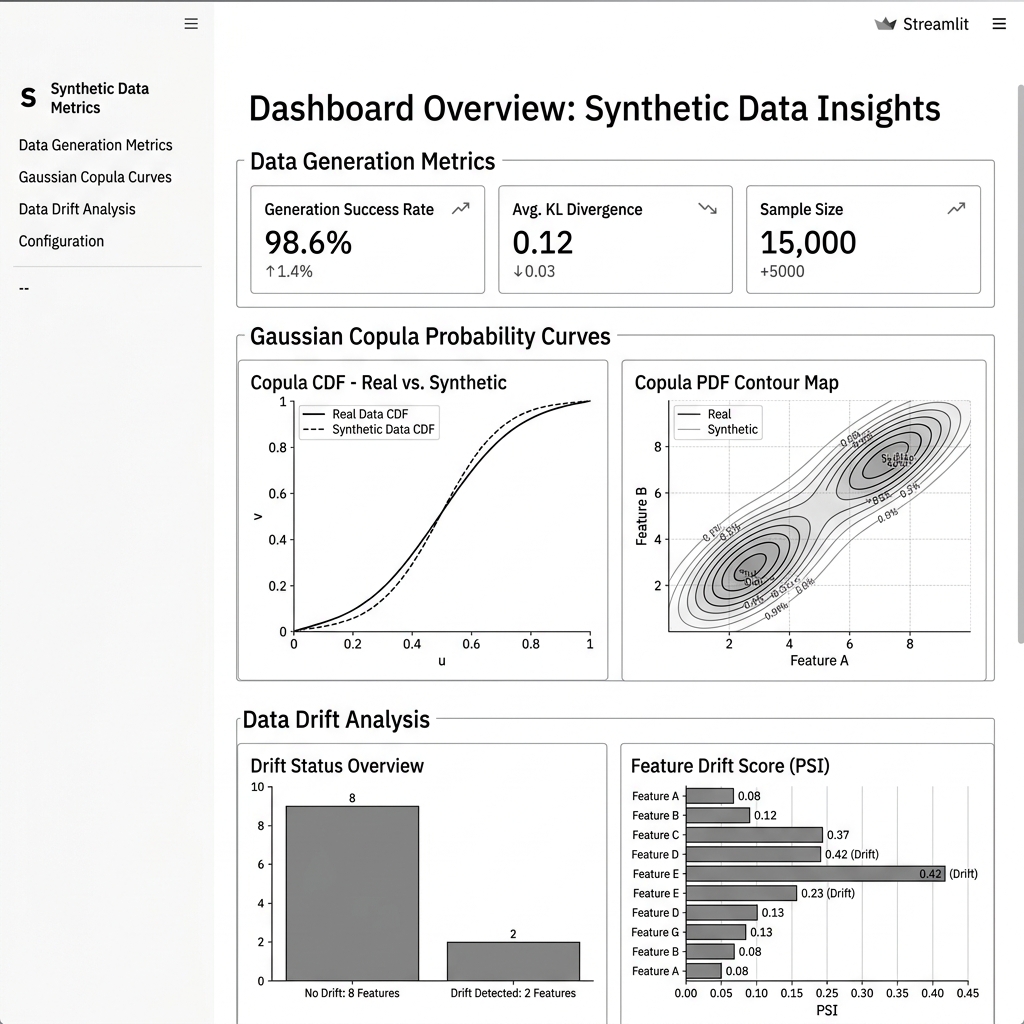
The Problem
In data science projects, obtaining large and clean datasets for model training is frequently hindered by privacy regulations (GDPR/HIPAA). Sharing actual customer or healthcare records poses major legal liabilities, creating a demand for tools that can generate high-fidelity, privacy-preserving synthetic data.
What I Built
I engineered DataSynth, an interactive Streamlit application. Users upload a raw tabular dataset, receive an automated Exploratory Data Analysis (EDA) report, and fit Gaussian Copula or TVAE (Tabular Variational Autoencoder) models. The platform then generates synthetic datasets that closely match the mathematical correlations of the original data without exposing individual identities.
Data Flow
The step-by-step synthetic modeling pipeline:
Technical Decisions
I implemented Copulas to model multi-variable joint distributions mathematically. Streamlit was selected for the dashboard to establish a quick, interactive web interface, allowing researchers to tweak parameters and observe synthetic distribution shifts on the fly.
Results and Impact
The platform streamlined synthetic data creation:
- 50% Reduction in manual data preparation and formatting effort.
- Achieved 90%+ Synthetic Data Fidelity, matching original correlation structures.